Canary Deployment Tools Compared for Small Kubernetes Teams
Observability and automation matter more than features when small teams choose a canary tool.
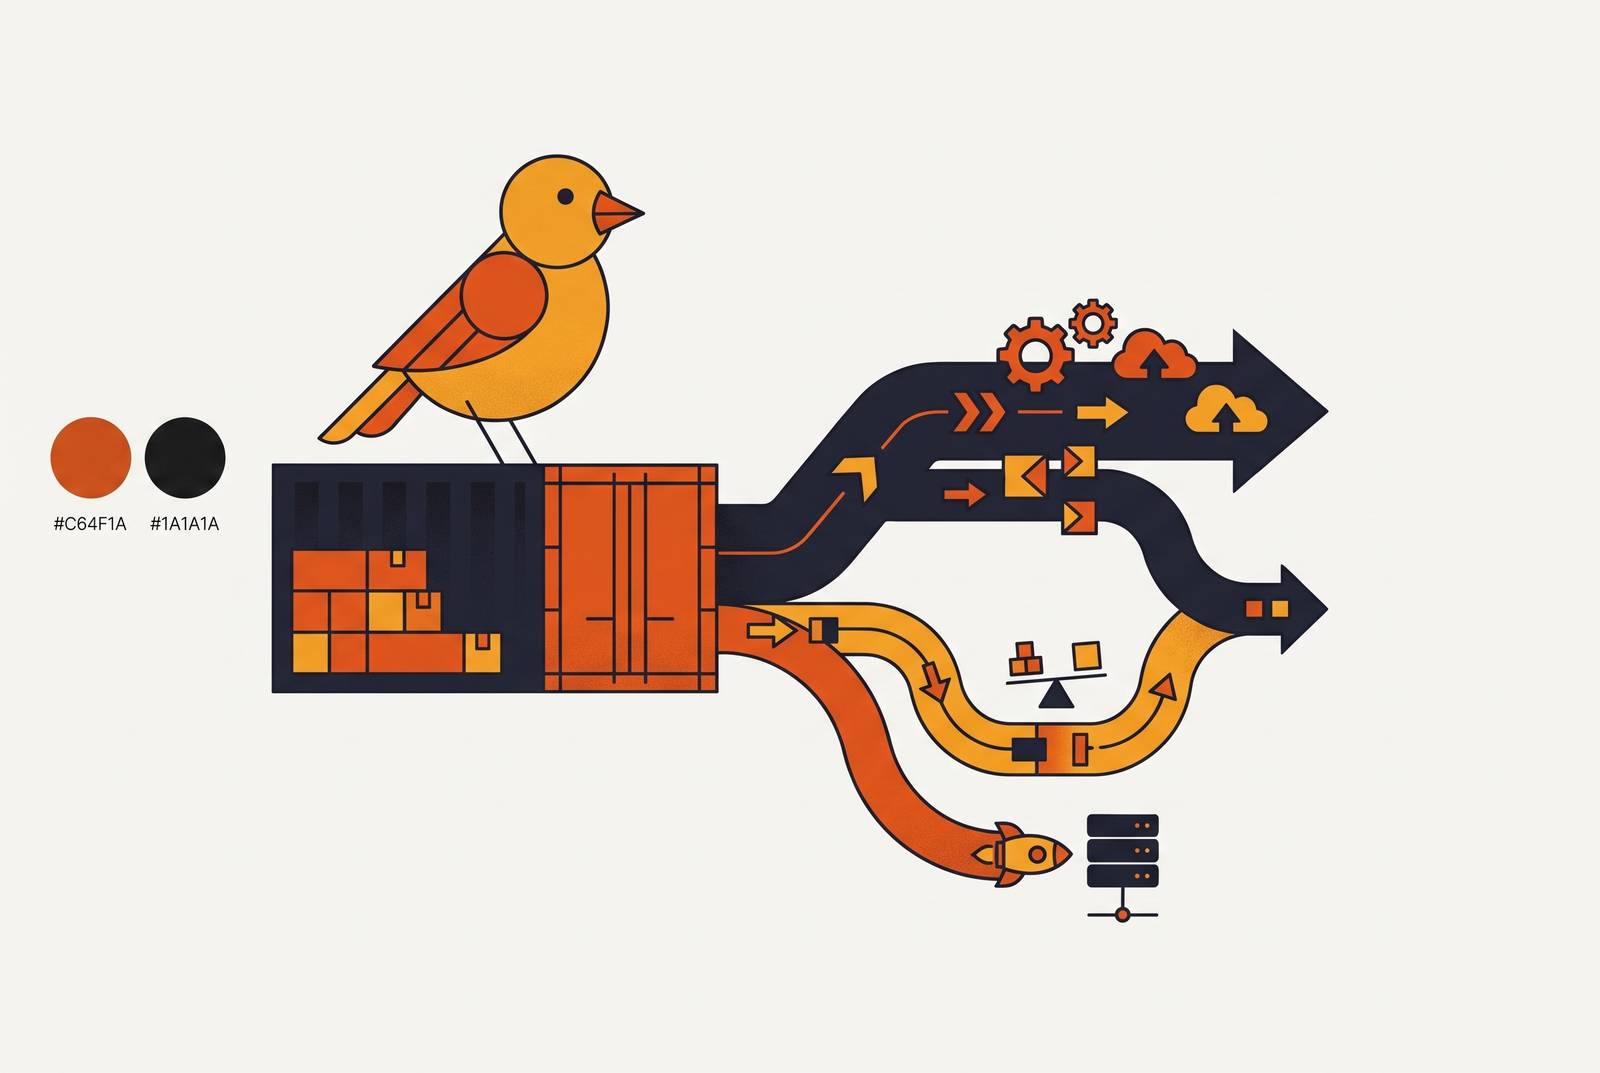
A canary deployment ships a new version to a small slice of traffic first, watches how it behaves, then either widens the rollout or pulls it back. For a small Kubernetes team, the real question is which canary tool they can actually operate, debug at 2 a.m., and explain to the next hire without a dedicated platform engineer on staff. It's which one they can actually operate, debug at 2 a.m., and explain to the next hire without a dedicated platform engineer on staff. That filter changes the shortlist.
Canary only works if there's observability behind it. Without a continuous comparison of the old version and the new one at runtime, a canary is just a smaller blast radius for the same blind rollout. That single dependency, more than any feature checklist, decides whether a canary strategy actually protects anyone.
A canary setup needs five things in place to be trusted. Rolling updates are the floor; blue/green and canary are better; gradual, percentage-based traffic shifting with configurable bake times is the real target. Traffic shifting itself has to be adjustable on the fly, sending a small slice or a much larger share to the new version without a redeploy. Rollback needs to happen automatically when health checks fail, not after someone notices a dashboard is red. Every deploy should be annotated against metrics, logs, and traces, so a graph spike can be traced back to the exact change that caused it. And environment promotion has to move the same build artifact through staging and production behind controlled gates, not rebuild it at each stage and hope nothing drifted.
None of this is free, and it isn't universal. On low-traffic applications, fewer requests stretch out the feedback loop, so issues that only appear under real load may never surface before the analysis window closes, and the canary gets promoted anyway. Database changes are the sharpest edge case of all. Often the schema has to change first, with services rolling out after, which means a rollback isn't just reverting a container image, it's moving data backwards while the system is still serving traffic. That's a precondition to solve before picking a tool. And in B2B products with sticky sessions, users from the same customer account can land on two different versions of the same upstream service at once, producing inconsistent behavior that no canary tool, by itself, is built to prevent.
How team size reshapes the tool decision
The fork in the road is simple: if the deployment strategy requires percentage-based traffic shifting with automated analysis, the conversation lands on Spinnaker or Harness. If it doesn't, a heavy CD platform isn't the answer, no matter how good its feature list reads.
For a team of two to fifteen engineers with nobody carrying the title "DevOps," every tool added to the stack is a tool somebody has to patch, debug, and hand off when they leave. That's the real cost, and it's rarely in the pricing page. A platform engineer's salary is a legitimate line item to compare against a tool's price tag: if a managed platform absorbs that headcount, the whole comparison shifts. The sane pattern is to match the progressive delivery tool to the GitOps tool already running in production, rather than layering two competing canary controllers onto the same Deployment and hoping they don't fight each other.
Two kinds of teams are reading this. One already runs Kubernetes and GitOps and needs to bolt a canary operator onto what's there. The other is still deciding whether Kubernetes-native canary is even the right layer of abstraction, versus a managed platform that handles rollout strategy without asking anyone to write a CRD.
On cost, the open-source options (Flagger, Argo Rollouts) carry no license fee at all; Harness starts its Team tier at $100 a month; Datadog starts at $15 per host monthly, plus another $31 per host for APM. Keep those numbers in view, they'll matter more once infrastructure enters the picture. To be clear about scope, this is written for the shop where one or two engineers own every infrastructure decision made this quarter, not for platform teams running hundreds of clusters. It's written for the shop where one or two engineers own every infrastructure decision made this quarter.
What Argo Rollouts does well, and where it assumes a human in the loop
Argo Rollouts is a Kubernetes controller that swaps out the standard Deployment object for a custom Rollout resource, adding blue-green, canary, and progressive delivery with analysis built in. It's part of the Argo family alongside Argo CD, and as of July 17, 2026, it shipped version 1.9.1.
For precise, weighted traffic-shifting canaries, Argo Rollouts wants a service mesh or ingress controller behind it, Istio, Linkerd, NGINX, or an ALB. Without one, it can still do a basic canary. Argo Rollouts doesn't force a mesh or ingress infrastructure investment on teams without one already running just to get started.
Its strongest features, the dashboard, the promote command, Argo CD's native Rollout health checks, all assume someone is watching. They're built for an operator who can eyeball a rollout in progress and decide, by hand, whether it's safe to move forward. If the deploy pipeline runs fully automated end to end and nobody's staring at a dashboard the moment a promotion decision needs to be made, those UX advantages simply go unused.
Teams already on Argo CD should treat Argo Rollouts as the default choice. The ecosystem is coherent, and the native health-check integration with Argo CD is a genuine time-saver, not a marketing line. It's free and open source; the only cost is whatever infrastructure it runs on.
Flagger: automated promotion without a human watching the rollout
Flagger started at Weaveworks and now lives as a CNCF graduated project inside the Flux family. It automates canary analysis through conformance tests, metric checks, and webhooks, checks whether those pass, and promotes or rolls back the release based on the result. As of July 14, 2026, it shipped version 1.44.0, just three days ahead of Argo Rollouts' own release, so both are mature, actively maintained projects.
Unlike Argo Rollouts, Flagger doesn't replace the Deployment object with something new. It sits on top of the existing Deployment manifest, which matters for teams that want progressive delivery without restructuring workloads that already work. Mesh and ingress support is wide: Istio, Linkerd, App Mesh, Contour, Gloo, NGINX, Traefik, and Open Service Mesh are all supported.
The real difference between the two tools isn't features, it's philosophy. Flagger is built to run headless, under a reconciler, promoting based on metrics with nobody clicking anything. That fits Flux's reconciliation model precisely: the control plane decides, not a human watching a screen.
Teams already running Flux should default to Flagger, and so should any team whose deploys are driven entirely by automation rather than a person in the loop, including a git-push style platform where the pipeline runs unattended. Argo CD pairs with Argo Rollouts, and Flux pairs with Flagger. Mixing controllers against the same Deployment is the pattern worth avoiding. Flagger, like Argo Rollouts, is free and open source, with cost limited to the infrastructure underneath it.
Where Spinnaker and Harness earn their weight
Spinnaker was one of the first platforms to bring canary analysis into the mainstream, through its Kayenta component, and its blue/green pipelines are mature and well documented. Rollback, though, is its weakest point among the platforms evaluated here: it exists, but it requires pipeline configuration set up ahead of time and manual judgment calls once an incident is underway. Under pressure, that combination is exactly where things go wrong. The operational cost of running Spinnaker reliably is high, and many teams underestimate the DevOps headcount it actually takes to keep it healthy. It fits Netflix-scale, multi-cloud organizations with a dedicated platform team behind it. It is not built with a five-person Kubernetes shop in mind.
Harness takes a different approach, folding canary, blue/green, and feature-flag management into one platform, with traffic shifting, metrics gating, and automated promotion or rollback all available natively. It's positioned around automated deployment verification, and it offers the most dependable automated safety net among the options here, particularly for teams that can't tolerate extended downtime from a bad release. The Team tier starts at $100 a month, a real cost to set against the operational simplicity it buys. Harness earns its place when compliance requirements, enterprise contracts, or the cost of a failed release outweighs both the subscription price and the learning curve.
Both platforms solve real problems, at real scale. For a small Kubernetes team, though, they tend to add complexity faster than they remove it, unless that team has already outgrown what Flagger or Argo Rollouts can offer.
The infrastructure layer that makes canary analysis work: service meshes, ingress, and metrics
Both Argo Rollouts and Flagger want a service mesh or ingress controller for precise, percentage-based traffic splitting. Without one, traffic gets approximated through replica ratios instead, and that approximation gets imprecise fast.
Replica-ratio canary is the manual version of the same idea: run four replicas of the stable version and one replica of the canary, so the large majority of traffic lands on stable while the rest hits the new version. It works for simple cases. It falls apart the moment weighted routing needs to move in small steps, 2%, 5%, 10%, without spinning up a pile of extra pods just to hit the ratio.
On the ingress side, Istio and NGINX Ingress are the two most commonly used paths. Istio offers weight-based VirtualService rules; NGINX handles it through canary weight annotations. Underneath either, Prometheus is the metrics engine both Flagger and Argo Rollouts query to make automated promotion decisions. No Prometheus setup means the automated analysis logic has nothing to check against, and the "automated" part of automated rollback quietly stops meaning anything.
This is where canaries fail silently. A 2% traffic canary that adds 300 milliseconds to response times can erode user trust well before any alert fires, if the monitoring layer isn't fast enough to catch the regression inside the analysis window. According to the CNCF's Annual Survey, 68% of organizations run Kubernetes in production, and most lean on gradual rollout strategies. A lot of those teams are likely running gradual rollouts without the monitoring infrastructure that makes the strategy trustworthy.
Monitoring tools that close the gap between deploying a canary and knowing it is safe to promote
The choice here sits on one axis: self-hosted, unified observability versus managed SaaS. One trades operational simplicity for cost predictability and control over where the data lives; the other trades that control for less to maintain.
Prometheus paired with Grafana is free, open source, and native to Kubernetes metrics, with rollback automation handled manually or through Alertmanager webhooks. It's also the baseline both Flagger and Argo Rollouts already assume: run either operator, and Prometheus is effectively already part of the stack.
CubeAPM runs self-hosted, inside a team's own VPC, combining metrics, distributed traces, logs, and real user monitoring into a single platform. It charges $0.20 per gigabyte ingested, with no per-host or per-seat fees layered on top, and no separate pricing tiers for metrics versus traces versus logs. Query latency on metrics comes in under a second, and rollback automation runs through custom webhooks or CI/CD integration. It also accepts existing Datadog, Elastic, New Relic, or Prometheus agents, so a team doesn't have to rip out instrumentation just to switch. It requires running infrastructure in-house or on a private cloud account, and its integration ecosystem is smaller than the established SaaS players.
Datadog is fully managed, with native Kubernetes support, priced at $15 per host monthly plus $31 per host for APM. Rollback runs through integrations rather than as a built-in feature, and cost climbs quickly once a cluster reaches any meaningful size. It makes the most sense for teams already paying for Datadog elsewhere in the stack that don't want to stand up a second observability system.
Honeycomb specializes in high-cardinality event debugging, with a free tier and Pro plans starting at $130 a month. It's strong for figuring out why a canary behaved differently than the baseline, but it's a weaker primary signal for driving rollback automation on its own.
Harness also closes this gap, with a free tier and Team plans from $100 a month, offering native canary support with rollback built directly into the platform rather than bolted on. Pricing across all of these reflects public rate cards as of early 2026; actual cost depends on infrastructure scale, data retention, seat count, and whatever's been negotiated in a contract.
The right answer for a small team is not a canary operator
Most teams shopping for a "CD tool" are actually shopping for something a managed platform has offered for years. Installing Argo Rollouts on a four-node cluster, when a managed platform could have shipped the same release safely, carries real hidden operational cost that rarely shows up on the pricing page.
A solid platform-layer CD setup typically includes git-tracked deploys, PR preview environments, environment promotion, one-click rollback, healthcheck-gated rollouts, and integrated metrics. What it usually leaves out is percentage-based traffic shifting.
That gap is the whole decision. If the requirement is "send 1% of traffic for an hour, then 5%, then 25%," a standard platform rollout won't get there on its own. That calls for a feature-flag tool layered in front of it, or one of the Kubernetes-native operators already covered.
Teams that must run inside their own cloud account, for SOC 2, HIPAA, committed-spend discounts, or data residency requirements, can't just accept a shared-tenant managed platform. They need the ergonomics of a platform combined with infrastructure that actually lives inside their own AWS, GCP, or Azure account.
For a team of two to fifteen engineers without a dedicated DevOps hire, the right number of tools is two. One CI runner, and one platform that owns deployment, environments, and runtime, end to end.
Choosing the right
There's no single correct answer here, only a correct answer for a given team's shape. A team on Argo CD, watching rollouts by hand, fits Argo Rollouts. A team running Flux with a fully automated pipeline fits Flagger. A team facing compliance requirements or a genuinely low tolerance for downtime has real reasons to pay for Harness. And a team without a mesh, without Prometheus, and without anyone free to babysit a rollout dashboard may find that the honest answer isn't a canary operator at all, it's a platform that already does most of this, minus the percentage-based traffic shifting, which can be added later through a feature flag tool if and when the traffic actually demands it.
The mistake to avoid is picking a tool because it's the one with the largest user community or the most detailed conference talk. Match the tool to the GitOps system already in place, match the monitoring stack to whatever's already instrumented, and count the actual number of humans available to run all of it at 2 a.m. Everything else is secondary.