Railway Cost Breakdown at Scale and Which BYOC Platforms Handle the Migration for You
Managed BYOC cuts hosting markup by running your stack in your own cloud account.
Managed BYOC is the route to a PaaS-style deployment workflow in your own AWS, GCP, or Azure account without building the infrastructure management layer yourself. It removes the hosting vendor’s metered markup while leaving the underlying cloud bill in place. The financial case depends on how much that markup costs today and how much migration and ongoing operations the platform actually handles.
How metered PaaS pricing compounds as a stack grows
The advertised compute rate prices a component. A real invoice also includes the managed database, storage, and data leaving the platform. Compute can be the smallest of those charges. A configuration with two services, a managed database, and a cache therefore lands at a monthly cost that looks little like the headline per-service rate.
The database opens the first gap between expectation and cost. It is billed separately and often costs more than the application compute it supports, so the app’s advertised rate says little about the cost of running the product. Metering then adds another source of uncertainty. Instead of holding a fixed monthly budget, the team inherits the variance of traffic, including a launch, a crawler, or a retry loop that keeps resources busy.
Egress widens that gap as actual use grows. For apps serving images, video, or API JSON at production traffic volumes, outgoing data can become the dominant expense, ahead of both compute and the database. The team has to multiply the per-GB rate by everything the app sends, then add the charges for every other separately metered part of the stack.
Why egress and idle compute are not edge cases but structural costs
Always-on services use resources even when nobody uses them. Per-second billing on CPU and RAM keeps the meter running when things are quiet, so the team still pays when traffic is low. Two small always-on services can use up a platform credit tier before much traffic arrives.
Egress adds a different structural charge. In the shared-PaaS model described here, the vendor adds margin on top of the cloud provider’s own charge for outgoing data. The bill does not separate that margin. The customer sees the vendor’s per-GB rate, rather than a clear split between the underlying network cost and the hosting layer’s share. Sending the same data from the customer’s own AWS or GCP account avoids that additional layer.
Production database requirements compound the effect further. Adding failover or read replicas can trigger price cliffs rather than small increments, while storage grows on a meter independent of database compute. Taking more care with usage can cut waste, but the team still has to pay the charges built into the hosting model and meet standard production requirements.
Where the cost math breaks for AI and GPU workloads specifically
GPU workloads expose the same problem at a much higher resource price. GPU compute costs an order of magnitude more than CPU compute, making idle capacity far harder to absorb. A quiet inference endpoint can still be expensive. When a GPU pool stays on between requests, the team pays for availability whether or not enough useful work arrives to justify it.
The move from prototype to production makes that utilization gap more costly in absolute dollars. As infrastructure spending rises, vendor-metered pricing and cloud-direct pricing grow further apart. Account ownership becomes financially important. When the team pays a hosting vendor rather than its own cloud provider, it cannot use reserved instances, committed-use discounts, and startup credits from AWS Activate or Google for Startups to cut its infrastructure bill in the same way.
Control over configuration is just as important as the rate. Moving from always-on GPUs to a mix of on-demand and spot instances, with precision and batching improvements, requires access to settings that shared PaaS may not expose. Spheron’s own worked example illustrates that combination. Its H100 inference example moves from an always-on FP16 setup to FP8 and continuous batching, with on-demand H100 capacity and L40S spot capacity for batch jobs.
What BYOC actually changes about the cost structure
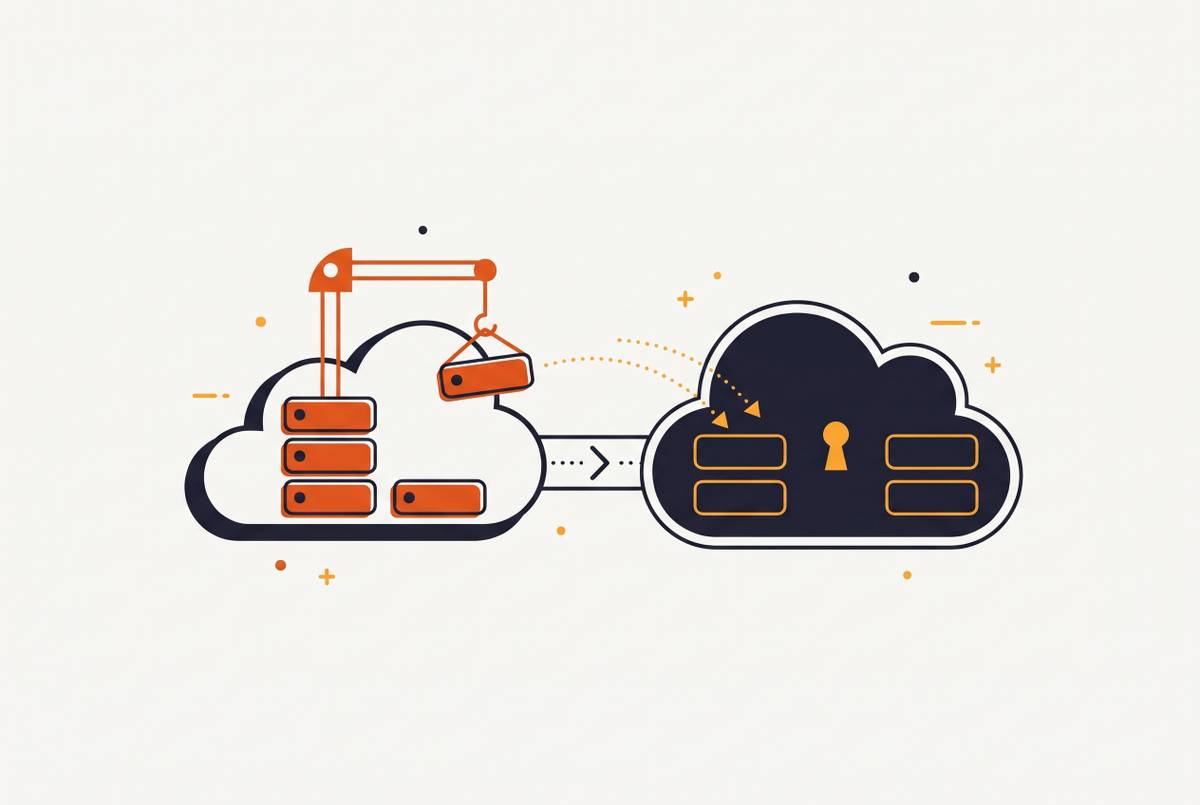
BYOC separates infrastructure ownership from platform management. The vendor runs the control plane, which handles orchestration, CI/CD, and routing decisions, while the customer’s VPC holds the data plane, including containers, databases, and load balancers. The billing split follows the architectural split. The customer pays the cloud provider for compute, storage, and egress, and pays the vendor a platform fee for management.
In the outbound-agent design described here, an agent inside the VPC polls the control plane to get instructions. The vendor does not need inbound network access. Traffic and data stay in the infrastructure layer that the customer controls, while deployment instructions come from the management layer. This arrangement removes the PaaS-layer egress markup, but the cloud provider’s standard egress charge remains.
Reserved instances, committed-use discounts, and Enterprise Discount Programs can apply to infrastructure in the customer’s account, and startup credits can help pay that account’s bill. Existing commitments gain another use as well. BYOC infrastructure can count toward Microsoft MACC and equivalent cloud commitments rather than becoming a separate hosting expense outside them.
Keeping the data plane in customer-owned resources narrows the infrastructure scope compared with relying on a shared-tenant platform, although compliance still requires attention to the management layer and the customer’s own controls. That distinction can unblock regulated deployments. For healthcare and financial services teams, the architecture can affect both the viability of the deployment model and the cost of the audit.
The platform’s operational scope determines how much of this benefit a small team can actually use. Managed BYOC can cover VPC setup, CI/CD, networking, autoscaling, cluster upgrades, and automatic CVE patching without requiring a dedicated DevOps hire. A platform that deploys containers into a customer’s account but leaves the customer to keep the infrastructure running gives the customer a different deal.
Flightcontrol provides a concrete AWS-only option, with git-push deploys, managed databases, autoscaling, and preview environments running in the customer’s account. It does not support GCP or Azure. Replit announced enterprise BYOC on October 16, 2026, with full-platform managed cells in an Azure, Google Cloud, or AWS tenant in private preview. Its other options, both in early access, place published apps in the customer’s tenant or provide an exported Docker image, Terraform configuration, and SBOM for the team to operate independently.
Those options serve different operational needs. Replit focuses on development and coding workflows rather than being a like-for-like production infrastructure management service. Coolify is self-hosted, leaving the server, upgrades, and operations to the team. It suits teams comfortable with that responsibility, but self-hosting is not managed BYOC. Cloud support, deployment features, and migration assistance therefore need separate evaluation.
AI inference platforms that pair with BYOC for GPU-specific workloads
A BYOC deployment platform can handle the application and API layer while a specialist platform handles GPU inference or training. The layers solve different cost problems. BYOC removes the hosting markup from customer-owned infrastructure, while per-second active-compute billing and scale-to-zero address GPU utilization. A specialist service does not automatically put its workloads in the customer’s own cloud account.
Modal supports production inference, training, and batch processing with serverless scale-to-zero, avoiding the need to keep GPU capacity running through idle periods. Modal reported completing its SOC 2 Type II audit with no deviations found. Cerebrium offers 12+ GPU types, including H100 and A100 configurations, with per-second billing for active compute and scale-to-zero.
Baseten holds SOC 2 Type II certification and supports HIPAA, making it relevant to regulated AI deployments. Separate training and inference providers are also viable. Lambda Labs has competitive prices for GPU instances, while Oracle Cloud charges more for H100 on-demand than specialist providers such as Lambda Labs. Teams that train elsewhere and serve inference on their primary cloud can make the two buying decisions separately.
The real cost of a BYOC migration: what teams underestimate going in
Building BYOC infrastructure can take many months of a small team’s focused engineering time and leave it with ongoing work to keep things running. A lower resource rate does not help if the team spends more maintaining infrastructure than it saves on hosting. The comparison has to include both the migration and the work that remains afterward.
Managed BYOC changes the scope of that objection. The platform absorbs cluster management, upgrades, network configuration, and CVE patching instead of asking the application team to build and maintain those systems. The team still has a migration project, choosing and adopting an existing management layer.
A vendor’s ability to provision a VPC or offer git-push deployments does not, by itself, establish that it will handle the application move. The distinction deserves a direct question. For a team choosing a platform, the relevant scope includes what the vendor handles during migration and what it continues to handle once production is running.
Day-two operations still test the platform’s design. Observability across the customer’s VPC boundary requires aggregated metrics and redacted traces without exporting customer data. A vendor serving environments with different versions and maintenance windows needs automatic upgrade handling, and that capability is not guaranteed merely because the product calls itself BYOC.
How to evaluate whether moving to BYOC is the right next step for your stack
A team should start with the current invoice and break out compute, database, storage, and egress charges to see whether the hosting margin is big enough to make migration work worthwhile. Egress deserves particular attention when it is a significant share of spending. A database bill that rivals or exceeds application compute is another signal that the headline service rate no longer describes the stack’s economics.
Unused AWS Activate or Google for Startups credits, cloud commitments the team already has, a compliance audit coming up, or EU data residency requirements can change the decision even before the team would save much on compute alone. These are distinct reasons to move. How much these help depends on whether the chosen platform supports the cloud the team needs and lets it keep control of the resources involved.
Staying on shared PaaS can still be the better choice. If the total bill is small, the platform margin may cost less than the engineering time required to migrate. Before product-market fit, making infrastructure more complex can also pose a bigger risk than the cost of hosting. A team in that position should weigh the work of migration against what it pays now, while leaving room to deal with future scale when it arrives.
When the economics do justify moving, the platform comparison should center on cloud support, migration assistance, and the ongoing work the vendor absorbs. Managed VPC setup, cluster management, CI/CD, and compliance tooling let the team focus on migrating applications. A familiar git-push workflow can remain intact. The decision is ready when the team can identify the charges it will remove, the cloud costs it will retain, and who owns the work after the move.